Today, we’re launching Operator-1, an autonomous document extraction agent. Operator-1 is SOTA on several 3rd party benchmarks and sets the new standard for accuracy on complex documents.
TL;DR
- What’s new: Operator-1 is an autonomous extraction agent that solves challenges within complex documents, such as long table extraction, large files with thousands of pages, dense diagrams and images, and more.
- How: A specialized agent runs within a purpose-built workspace, has access to document processing tools (parsing, search, code execution, validations), and learns via persistent memory.
- Best fit use cases: Long tables in financial statements, legal documents that run thousands of pages, and document packets that need nested JSON to preserve relationships.
- Results: Operator-1 sets a new standard for complex extraction, saturating three benchmarks with scores of 99.3% on LongArray-Extract, 99.88% on LongExtractionBench, and 96.57% on ExtractBench.
Operator-1 sets a new performance record across three extraction benchmarks
Operator-1 sets a new standard for complex document extraction, saturating three benchmarks: 99.3% on LongArray-Extract, 99.88% on LongExtractionBench, and 96.57% on ExtractBench. Each benchmark uses a different dataset and evaluation methodology; two of the three benchmarks were published by third parties.
| Benchmark | What it tests | Score |
|---|---|---|
| LongArray-Extract | Accurate and complete extraction of long arrays from real-world documents | 99.3% |
| LongExtractionBench | Filling JSON schemas from long documents | 99.88% |
| ExtractBench | Structured extraction across business documents | 96.57% |

LongArray-Extract
Aggregate accuracy
- 1Operator-199.3%
- 2Extend MAX99.2%
- 3Reducto Deep Extract97.4%
- 4Gemini 3.1 Pro · direct47.3%
- 5GPT-5.5 · direct31.6%


LongExtractionBench
Leaf accuracy
- 1Operator-199.88%
- 2Reducto Deep Extract99.3%
- 3GPT-5.5 · direct96.2%
- 3Gemini 3.1 Pro · direct96.2%
- 5Extend MAX92.8%
- 6LlamaExtract88.9%

ExtractBench
Overall value F1
- 1Operator-196.57%
- 2LlamaIndex Agentic Plus v2.596.38%
- 3LlamaIndex Agentic v2.595.8%
- 4LlamaIndex Cost Effective v2.593.9%
- 5Reducto Deep Extract90.44%
- 6GPT-5.5 · direct~88.7%
- 7Extend MAX86.29%
- 8Gemini 3.1 Pro · direct~78.2%
Published benchmark results, not a new head-to-head evaluation. Direct model baselines use single-shot extraction. ExtractBench includes LlamaIndex’s October 1 v2.5 results. For Operator-1’s ExtractBench result, we normalize null and empty responses because both indicate no extracted value for downstream applications. This yields 96.57%, compared with 96.4% without normalization. We plan to submit this scorer change as a PR to the ExtractBench repository.
LongArray-Extract was published by Extend. It is open source and independently reproducible, and we encourage you to evaluate it on your own documents. LongExtractionBench was published by micro1 and co-designed by Reducto. ExtractBench was published by LlamaIndex.
What Operator-1 solves
Existing extraction solutions break down on complex extraction tasks that require the highest levels of accuracy — financial tables that stretch for thousands of rows, long legal documents with related context scattered throughout, healthcare charts with dense figures and diagrams.
This is because traditional extraction relies on naive approaches (e.g. simple chunking, single-pass extraction with a model). This works on simple documents, but doesn’t handle hard edge cases found in many domains and is slow and expensive.
Long tables
We heard from many teams that extracting data from large tables (e.g. in finance or insurance) with hundreds or thousands of rows often runs into issues with skipped entries, duplicate information, or incorrect data.
Operator-1 parses documents to identify table structures, executes scripts to map and extract data, and even inspects page breaks to ensure that data isn’t lost across boundaries. It can even run validations to check its work iteratively (e.g. sum the line items and ensure it adds up to the total).
Lengthy documents
Documents with hundreds or thousands of pages are challenging to extract from because information is typically scattered across multiple sections. Operator-1 parses documents and searches across the text to identify the right pages in files that run thousands of pages.
Dense images and diagrams
Some documents can contain very dense images, diagrams, or charts (such as those within healthcare or construction).
Operator-1 can zoom in/out of images and crop regions of a page to better inspect text hidden within these areas.
How we built Operator-1
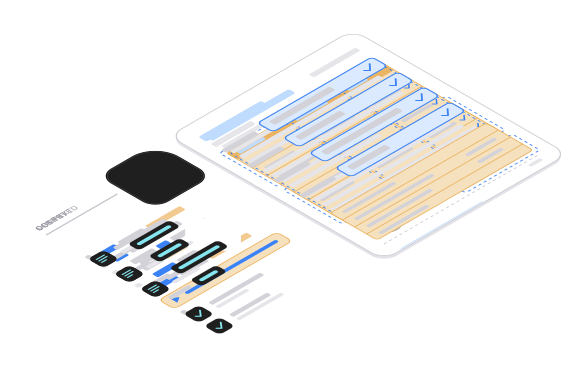
Operator-1 is a specialized agent that runs within a dedicated workspace we built specifically for document extraction. It has access to tools like:
| Tool | What Operator-1 uses it for |
|---|---|
| Inspection | View page breaks and other page region crops |
| Parsing | Makes document content available for extraction |
| Code execution | Writes and executes scripts to validate and transform data according to the extraction task at hand. |
| Search | Uses command-line and custom search tools to find and connect information across thousands of pages |
| Validations | Checks results against the task’s requirements and triggers another attempt when a check fails |
| Memory and runbooks | Remembers the code and approach that worked for a document type for subsequent extractions |
Pricing & availability
Operator-1 is available today in the Extend dashboard and API. It’s included on all our plans, including PAYG, Scale, and Enterprise. Operator-1 charges a fixed 5 credits per page.
Memory and runbooks let Operator-1 reuse an approach that worked for a document type. As Operator-1 learns from previous runs of a document type within your tenant, it can reuse successful strategies and work more efficiently over time.
Get started for free
We’re on a mission to help our customers automate every document. Put Operator-1 to work on your hardest documents: Try Extend.
Start building with Operator-1
from extend_ai import Extend

result = Extend().extract_runs.create_and_poll(
    config={
        "base_processor": "extraction_operator",
        "schema": {
            "type": "object",
            "properties": {"total": {"type": ["number", "null"]}},
        },
    },
    file={"url": "YOUR_DOCUMENT_URL"},
)
print(result.output.value if result.output else result.status)import { ExtendClient } from "extend-ai";
const result = await new ExtendClient().extractRuns.createAndPoll({
config: {
baseProcessor: "extraction_operator",
schema: {
type: "object",
properties: { total: { type: ["number", "null"] } },
},
},
file: { url: "YOUR_DOCUMENT_URL" },
});
console.log(result.output?.value ?? result.status);extend extract document.pdf \
--config '{"baseProcessor":"extraction_operator","schema":{"type":"object","properties":{"total":{"type":["number","null"]}}}}' \
> result.json{
"mcpServers": {
"extend": {
"url": "https://mcp.extend.ai/mcp"
}
}
}