Extract API
Pull typed JSON out of documents with citations
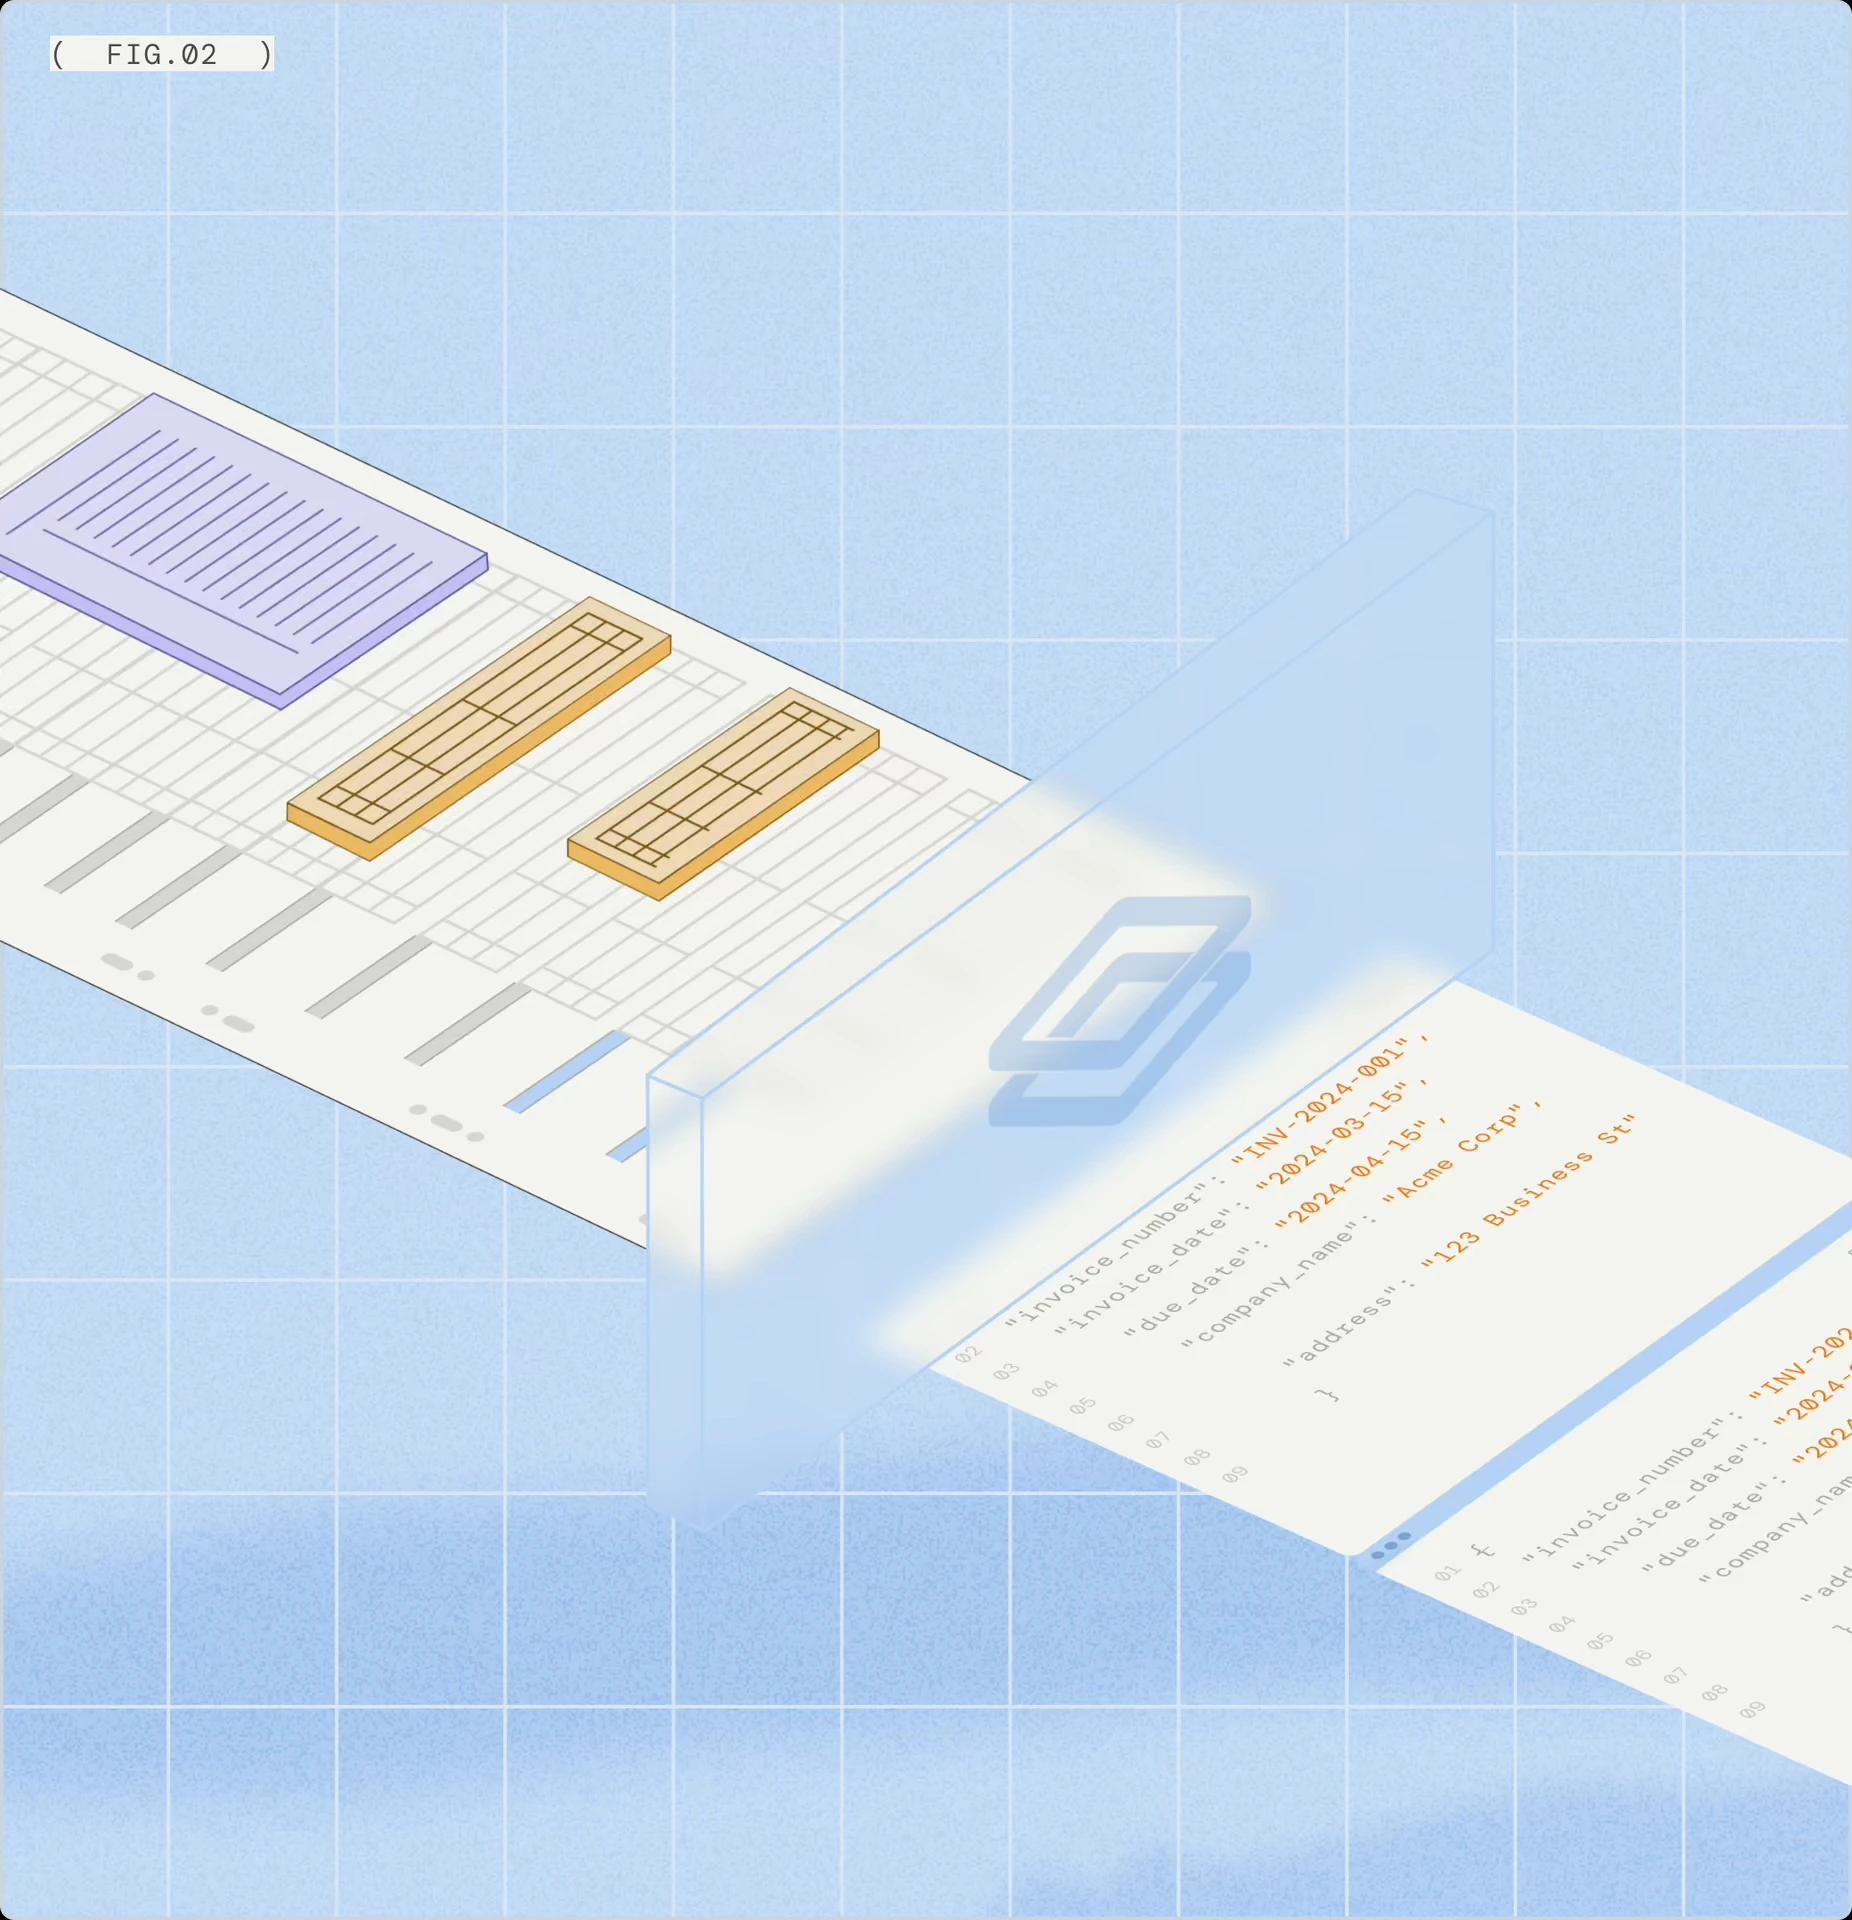
Your JSON schema defines the output; Extract fills it from the document and returns per-field confidence and bounding box citations so your team can trust every value.
What it does
Schema in, typed JSON out
Output matches the shape of your schema. Omit the schema and Extract infers one from the document.
Confidence and citations
Per-field model and text-recognition confidence, plus bounding box citations, show where each value came from.
Packages of files
Pass several files in one run when a single record spans more than one document.
Under the hood
Extract structured data from documents into any schema.
Scale to 1,000+ page files
Smart chunking & merging strategies ensure accurate extraction without hitting token output or context limits.
Extract large tables
Choose from multiple array extraction strategies, capable of extracting 1,000+ rows accurately across 100s of pages.
Precise bounding boxes
Dedicated citation model generates granular citations for every extracted value, even inferred ones.
Low latency processing
Fast mode extraction for real-time use cases.
Model-agnostic by design
New foundation models are continuously benchmarked and integrated. Evaluate performance and upgrade versions safely.
Benchmarks
LongArray-Extract
99.2%Mean extraction accuracy
45 financial, clinical, and legal PDFs with repeated arrays of 27 to about 2,200 records.
LongArray-Extract
100%Run completion, 45 of 45 documents
Failed and timed-out runs score zero, so completion counts toward accuracy.
How to get started
Create an account
Sign up at dashboard.extend.ai. New accounts get 10,000 free credits.
Copy an API key from the Developers page and export it as EXTEND_API_KEY.
Choose how to call Extract
Studio: try Extract in the browser with no code.
MCP: connect Claude, Cursor, or any MCP client to https://mcp.extend.ai/mcp.
CLI: install with curl -fsSL https://extend.ai/install.sh | sh, then run extend setup.
SDKs: pip install extend-ai or npm install extend-ai; Java and Go SDKs are also available.
Process your first document
Send a file and a minimal schema; the response holds a value for each schema property.
curl -X POST https://api.extend.ai/extract \ -H "Authorization: Bearer $EXTEND_API_KEY" \ -H "x-extend-api-version: 2026-02-09" \ -H "Content-Type: application/json" \ -d '{ "file": { "url": "https://extend-public-files.s3.us-east-2.amazonaws.com/bill-of-lading.pdf" }, "config": { "schema": { "type": "object", "properties": { "load_number": { "type": ["string", "null"], "description": "The load number." } } } } }'Move to production
Send production traffic to POST /extract_runs; the synchronous POST /extract times out after 5 minutes.
Documentation
Use cases
- Financial services
Invoice & AP automation
Pull header fields, taxes, and every line item into typed JSON with citations.
- Nuvocargo case study
Freight & cross-border documents
Pull shipment, carrier, and customs fields from bills of lading and invoices.
- Flatiron Health case study
Clinical & lab reports
Pull biomarker results from long NGS reports across hundreds of genes.
- Checkr case study
Background screening
Extract identity, employment, and record details from screening documents.
- HomeLight case study
Real estate contracts
Pull parties, dates, prices, and contingencies from purchase agreements.
- LongArray-Extract benchmark
Long transaction lists
Return every row from statements and ledgers with thousands of records.